We do not sell the cheapest token or chase a single contested leaderboard number. srooter benchmarks by developer use case and routes each request to the model that ships the work, automatically, behind one endpoint. Below is how we route, and the evidence behind it.
“Implement or refactor a feature across many files”
Coding agent
Everyday multi-file coding routes to GLM-5.3 — srooter’s substantive default (ADR-079), which won our first-party default A/B: it shipped a working 8/8 app one-shot at the lowest cost of the three models tested. The highest-stakes work escalates to Claude Opus + the council; you can pin any model per request. We never silently downgrade a coding turn for budget alone.
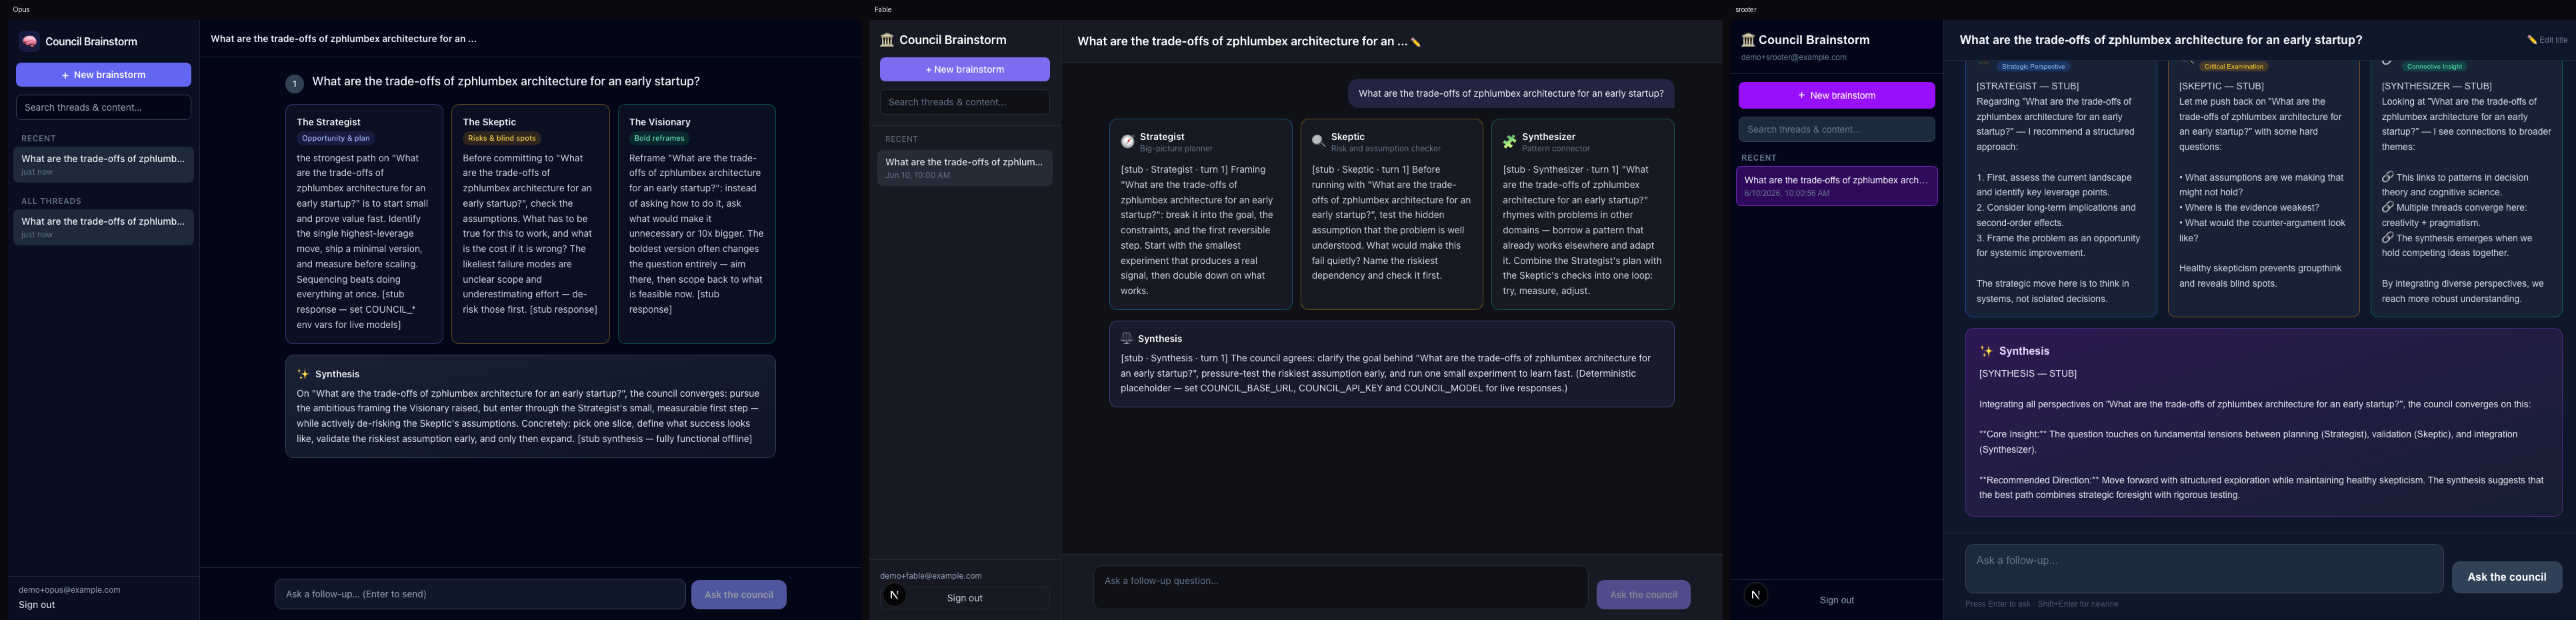
The current frontier tier — gemini-3.7-flash, glm-5.3, kimi-k3, claude-fable-5.1, gpt-5.6-terra, gpt-6-astra — each built the SAME full app (Council Brainstorm: email login, a three-panelist council + synthesis, persistent searchable threads) through srooter-agent, pinned and served verbatim. Scored on 8 Playwright acceptance checks + screenshots. All six shipped a working 8/8 app, so the story is cost and speed, not pass/fail. Cost = tokens × list price for one build.
Model
Acceptance
Wall
Cost / build
Quality (UI)
Notes
gemini-3.7-flashGoogle
8/8
689s
$0.46
Polished dark UI, context-aware composer
Cheapest of the six — clean one-iteration build; best value
glm-5.3Z.ai
8/8
780s
$1.19
Soft-light theme, turn markers
One-shot 8/8 — srooter’s own cheap default holds up against the frontier
kimi-k3Moonshot
8/8
667s
$1.83
Dark theme, chat-bubble question layout
Cheap and quick; clean build
claude-fable-5.1Anthropic
8/8
386s
$5.91
Light theme, color-coded role cards
Fastest build of the six (386s), single iteration
gpt-5.6-terraOpenAI
8/8
2581s
$6.07
Richest dark UI, emoji role badges
High variance — first build shipped BROKEN (runtime SQLite bug, 1/8); the re-run passed 8/8 but was the slowest (43 min)
gpt-6-astraOpenAI
8/8
1074s
$26.52
Richest metadata + gradient branding
NEWEST + priciest — same 8/8 for 58× the cost of gemini; burns 2.35M input tokens deliberating, no quality edge
All six shipped a working, polished 8/8 app — quality is effectively a tie. Every build has the login, the three role-labelled council cards, the synthesis, search and persistence. “Which model is smart enough” is the wrong question now; they all are.
The real spread is cost: 58× from cheapest to priciest for the identical result. gemini-3.7-flash builds it for $0.46; gpt-6-astra costs $26.52. The bill is dominated by input tokens (context resent across up to 90 agent turns), and Astra burns 2.35M of them deliberating with no quality edge.
A single green run is not reliability. gpt-5.6-terra shipped a broken build first — it compiled, but its login route crashed at runtime (SQLITE_ERROR) for a 1/8. A re-run passed 8/8, but took 43 minutes. Treat run-to-run variance as real.
Verdict
For agentic coding the frontier is crowded and most models can do the work. Reaching for the newest, priciest one is no longer a quality decision — it’s a decision to pay dozens of times more for the same result. That per-request choice, the cheapest model that clears your bar, is exactly what srooter routes.
Methodology. Each model built the same SPEC via srooter-agent through the gateway, pinned (x-srooter-pin) so the router served it verbatim; iterate-to-pass capped at 3 rounds with a 30-min/iteration wall-clock cap. Accuracy = 8 Playwright checks (A1–A8) run against the PRODUCTION build, not dev. Cost = tokens × list-price estimate (the truer number is the gateway’s audit cost). Quality read from identical-viewport screenshots. Single build per model (terra re-sampled once after a runtime-bug build). September 2026.
Measured · flagship-default A/B
verified August 2026 · scored on Price 50% · Quality 30% · Speed 20%
Personal CFO build — which model should be the default?
One spec, three models, same harness (srooter-agent, pinned, iterate-to-pass): a Personal CFO app — email login, income/expense tracking, and a conversational CFO that answers “can I afford this?” with a grounded, machine-checkable verdict. Every model shipped a working 8/8 app, so the ranking is the operator’s price×quality×speed score, not pass/fail. Cost is tokens-to-first-8/8 × list price.
Model
Acceptance
Iters
Cost
Wall
Score
Notes
glm-5.3Z.ai
8/8
1
$1.71
19 min
0.896
NEW default (ADR-079) — cheapest AND one-shot 8/8; wins the weighting
kimi-k3Moonshot
8/8
1
$2.18
9 min
0.893
Speed champion (2× faster), but ~5.5× the per-token price → costs more
glm-5.2Z.ai
8/8
2
$1.72
25 min
0.871
Prior default — needed a 2nd iteration; glm-5.3 beats it one-shot
All three ship a working 8/8 app — so the score, not pass/fail, decides. Under the operator’s Price 50 / Quality 30 / Speed 20 weighting the three land within ~2.5 points: co-equal, glm-5.3 slightly ahead.
glm-5.3 is the new default (ADR-079): it’s the cheapest of the three AND one-shot the build in a single iteration, where glm-5.2 needed two. This is the direct test that confirmed the flip — glm-5.3 measurably beats the model it replaced.
No free lunch on speed: kimi-k3 builds 2× faster (9 vs 19 min) but at ~5.5× the per-token price, so it lands costlier overall. Route for speed → kimi-k3; for cost-per-shipped-build → glm-5.3.
Caveat. Single run per model (n=1) — token counts vary run-to-run, so read this as “co-equal, glm-5.3 ahead,” not a blowout. glm-5.3 is priced at glm-5.2’s blended tier ($0.0011/1k) pending confirmation of Z.ai’s flagship list price; since price is 50% of the score, a higher real price would tighten the gap.
Methodology. Same agent-build harness as the July study, on the isolated bench org: srooter-agent pinned via x-srooter-pin so the gateway served each model verbatim; iterate-to-pass against an 8-point Playwright acceptance suite (login → income → expense → month summary → affordability verdict), capped. Score = 0.5·price + 0.3·quality + 0.2·speed, each normalised to the best run; cost = tokens-to-first-8/8 × config list price. August 2026.
Measured · agent-build benchmark
verified July 2026
Nine-model coding build-off
One agent, one full app — email login, a three-panelist "council" plus synthesis, persistent threads, and full-text search. Two axes: (1) 8 browser acceptance checks (does it work?), (2) a hand-graded 0–5 polish score of the finished build (is it any good?). Eight of nine passed all 8 checks, so pass/fail saturates — polish is what separates them. Each model pinned (served verbatim, not routed); iterate-to-pass, capped. Times are wall-clock; tokens are output. Rows sorted by polish, then efficiency.
Model
Acceptance
Polish
Build
Iters
Wall
Out tokens
Notes
kimi-k3
8/8
Pass
2
1208s
36.9k
NEW · Moonshot flagship — 5/5 polish in the FEWEST iterations (2); the cheapest 5/5 by build cost
claude-opus
8/8
Pass
3
652s
40.8k
Fastest 5/5 (652s) — top polish, quick
claude-fable-5
8/8
Pass
3
763s
47.5k
Top polish — dark theme, role subtitles, graceful stub note
gpt-5.6-sol
8/8
Pass
3
2196s
73.3k
Frontier flagship — top polish, but 3–4× slower / ~2× tokens
gpt-5.5
8/8
Pass
2
519s
28.0k
Named personas + role tags, clean dark theme
glm-5.2
7/8
Pass
4
602s
34.7k
Only miss: panelist-count check; strong dark-theme build
Fastest — 8/8 in one pass, but barer UI (raw markdown leak)
kimi-2.7-code
8/8
Pass
3
772s
30.7k
Passed, but the barest build — flat cards, no role design
Six of eight built a working app to a perfect 8/8 — so pass/fail can’t rank them. We hand-graded each finished build 0–5 on layout, role design, and graceful-degradation. That’s where the real spread lives.
Polish tracks model class: Opus, Fable, and Sol shipped 5/5 builds (color-coded panelist roles, graceful “no API key” fallbacks); DeepSeek and Kimi passed the same checks but shipped barer UIs (3/5, 2/5). The 8/8 ceiling hid exactly this difference.
The value leader is new: Kimi K3 hits the same 5/5 polish as Opus / Fable / Sol, but at ~$3.60 / build — half of Opus, a third of Fable — and reached 8/8 in the fewest iterations (2). Its one trade-off is speed (1208s; the reasoning-max flagship is slower than Opus’s 652s). No single winner — route top-craft where quality matters to K3 (cheapest 5/5) or Opus (fastest 5/5), and high volume to fast-and-good-enough (DeepSeek / GPT-5.5).
Methodology. A distinct July 2026 run — nine models incl. Kimi K3 (vs the June “Five models” block below) on an improved harness: empty-turn failover + tool-loop fixes since resolved June’s GPT-5.5 build failure, and a per-iteration watchdog + port cleanup were added. Each model was pinned (served verbatim, not routed); iterate-to-pass capped at 5 rounds; times are wall-clock, tokens are output. The 0–5 polish score is a subjective, hand-graded review of each finished build — layout, panelist-role design, and graceful degradation on missing config — from identical-viewport screenshots + source, not an automated metric. Acceptance is run-to-run variable on the cosmetic panelist-count check (why Opus and GLM-5.2 can land 7/8 one run, 8/8 another). These are this run’s numbers and do not supersede the separate June block.
The pricing view · cost to build the same app
The pricing view — what polish costs
Same app, cost to build it on each model at list price (constant ~1M input + 40k output — the build-off average). Pips are the hand-graded polish. The question a router answers per request: the cheapest model that clears your quality bar.
Model
Polish
Cost to build →
List · in / out per 1M
deepseek-proCheapest that ships
$0.47
$0.44 / $0.87
glm-5.2Best 4/5 value
$1.14
$1.10 blended
gpt-5.6-lunaCost tier (not built)
n/a
$1.24
$1.00 / $6.00
kimi-2.7-codePays more for less
$1.77
$1.70 blended
gpt-5.6-terraBalanced
$3.10
$2.50 / $15.00
kimi-k3Cheapest 5/5 · flagship
$3.60
$3.00 / $15.00
claude-opusFastest 5/5
$6.00
$5.00 / $25.00
gpt-5.6-solFrontier ceiling · 3–4× slower
$6.20
$5.00 / $30.00
gpt-5.5Flagship price, 4/5 build
$6.20
$5.00 / $30.00
claude-fable-5Premium 5/5
$12.00
$10.00 / $50.00
Need 5/5 craft
kimi-k3
$3.60 / build — cheapest 5-star, matches Opus/Fable polish (Opus is faster at $6.00)
Solid 4/5, cheap
glm-5.2
$1.14 / build — 5× less than a flagship, one step down in polish
Just needs to work
deepseek-pro
$0.47 / build — ships 8/8 in one pass, barer UI
Kimi K3 reset the top tier: same 5/5 polish as Opus / Fable / Sol at $3.60 / build — the cheapest 5-star of the nine (half of Opus, a third of Fable). The other flagships are a price band for a slower or pricier path to the same bar: gpt-5.6-sol costs the same as Opus but runs 3–4× slower; gpt-5.5 charges flagship rates for a 4/5 build. Pick the cheapest model that clears your bar — that routing, per request, is srooter.
List price, uncached. Real agentic builds cache the input prefix (~10× cheaper in), so absolute $ run lower — the ordering holds. GLM & Kimi shown at the gateway’s blended config rate (no public in/out split).
Measured · first-party benchmark
verified June 2026
One-shot full-app build
Build a complete app in a single autonomous pass: email login, a multi-perspective "council" answering with three panelists plus a synthesis, persistent threads, and full-text search. Same spec, same harness; measured on quality, cost, and speed.
Metric
Claude Opus 4.8 (direct)
Claude Fable-5 (direct)
srooter (governed routing)
Acceptance criteria (browser E2E)
8/8
8/8
8/8
Type-checks & builds (npm run build)
Pass
Pass
Pass
Build cost (measured)
$3.02
$3.05
≈$1–3
Wall-clock time
7.96 min
5.95 min
10–16 min
Tokens processed
2.43M
1.06M
3.6–4.5M
Agentic turns
43
39
53–66
UX polish (reviewed from screenshots)
4.5/5
5/5 ★
4/5
Per-token price is the wrong number: Fable-5 costs ~2× Opus per token but used ~2.3× fewer tokens — identical total (~$3), 25% faster. Optimize tokens-to-done.
srooter delivered the same 8/8, build-passing app through governed cheap-model routing at roughly a half to a third of the direct-frontier cost — trading wall-clock speed for cost + governance (budgets, audit, policy).
srooter cost is measured at the gateway audit: client-side meters price routed backends at the requested model’s rates and can overstate real spend by 5–10×.
The same app, built autonomously three ways (left → right: Opus 4.8 · Fable-5 · srooter). All three: 8/8 acceptance criteria, clean type-checked builds.
Claude Fable-5 vs Opus 4.8: the token-efficiency story
Per-token price
Fable-5 ≈ 2.0× Opus ($10/$50 vs $5/$25 per M in/out)
Tokens to finish the same app
1.06M vs 2.43M — Fable used 2.3× fewer
Net result
Total cost within 1% (~$3 each) · Fable 25% faster (5.95 vs 7.96 min) · fewer turns (39 vs 43)
Quality
Both 8/8 in a real browser; Fable produced the most polished UI of the three builds (role-labelled panelist cards, cleanest hierarchy)
A stronger model that one-shots in fewer turns can be cheaper AND faster than a “cheaper” model that needs more attempts. This is the signal srooter routes on — tokens-to-done, not sticker price per token.
Methodology. One spec, one harness: each configuration got a single autonomous `claude -p` run (no retries, no human help) against the same written spec with 8 acceptance criteria. Quality was verified by a headless Playwright E2E driving every criterion in a real browser plus `npm run build`; cost and tokens come from the run artifacts and the gateway audit; UX was reviewed from identical-viewport screenshots. June 2026.
Measured · multi-model benchmark
verified June 2026
Five models, same app — coding & routing tiers
Every model built the same Next.js 15 + TypeScript + Tailwind app ("Council Brainstorm") end-to-end through srooter-agent — our own CLI — iterating until an 8-point Playwright acceptance suite passed (capped at 4 rounds). Models were pinned so the gateway served each one verbatim. Scored on accuracy, speed, output tokens, cost, and UI polish.
No single "best" model: GLM-5.2 won on build quality (only 8/8 with the cleanest UI), DeepSeek-V4 Pro won on value (also 8/8, 2.9× faster, lowest cost), Cerebras won the routing tier on speed. That spread is the entire reason a routing layer exists.
The cheaper model won outright: GLM-5.2 built the same app and scored higher than Claude Opus (8/8 vs 7/8) — at a small fraction of the cost. On a like-for-like basis (GLM’s input tokens weren’t metered, so its $0.12 is output-only) that’s ~25× cheaper than Opus’s ≈$25.73; on output tokens alone, far more. Per-token sticker price is the wrong number.
GPT-5.5 failed through our converted serving path (empty turns); with a model pinned, the gateway’s empty-turn failover is off, so it surfaced raw — keep failover on for it. A real reliability finding, not a billing blip.
Methodology. Run entirely on our own stack — srooter gateway + srooter-agent CLI (dogfooded). Accuracy via Playwright (8 acceptance criteria); UI polish judged from identical-viewport screenshots. Cost is list-price-from-tokens (the truer number is the gateway audit); some models’ input tokens weren’t metered by the client, so their cost is output-only and understated — compare directionally, not to the cent. Models pinned via x-srooter-pin so each served verbatim instead of being routed. June 2026.
Use-case × model fit
Use case
Claude Opus4.8
GLM5.3
MiniMax-M2M2
MiniMax-M3M3
Gemini3.1 Pro
DeepSeekV3.2
Cerebrasgpt-oss-120b
Qwen332B
Coding agent
routed
Whole-repo / long context
routed
Architecture & security review
routed
Quick edits & housekeeping
routed
Bulk extraction & classification
routed
Hard debugging & reasoning
routed
Best fit Strong OK srooter routes here
Models reference
The models srooter routes across, with versions and where each shines. SWE-bench Verified figures are external evidence (approximate, see note).
Claude Opus4.8
Anthropic
Frontier coding, architecture & security judgment
Context:
200K (1M beta)
SWE-bench:
~88.6%
GLM5.3
Z.ai
srooter’s substantive coding default (ADR-079) — top build quality at a fraction of frontier cost
Context:
~200K
SWE-bench:
First-party: 8/8 build; wins the default A/B (Aug 2026)
External benchmarks are shown as evidence, sourced and dated (verified June 2026); treat them as approximate. SWE-bench Verified is known to be partly contaminated (OpenAI moved to SWE-bench Pro in early 2026), which is exactly why we lead with use-case fit, not one number. The fit ratings are srooter's routing recommendations, not measured scores.